/Proof
AI Use Case Prioritization Matrix For Marketing Teams
An AI use case prioritization matrix scores candidate ideas on impact and feasibility so a marketing team can choose one pilot to run this quarter.
Short answer
An AI use case prioritization matrix scores candidate ideas on impact and feasibility, then sorts them into four quadrants. The goal is to choose one use case worth piloting this quarter, not to rank every idea.
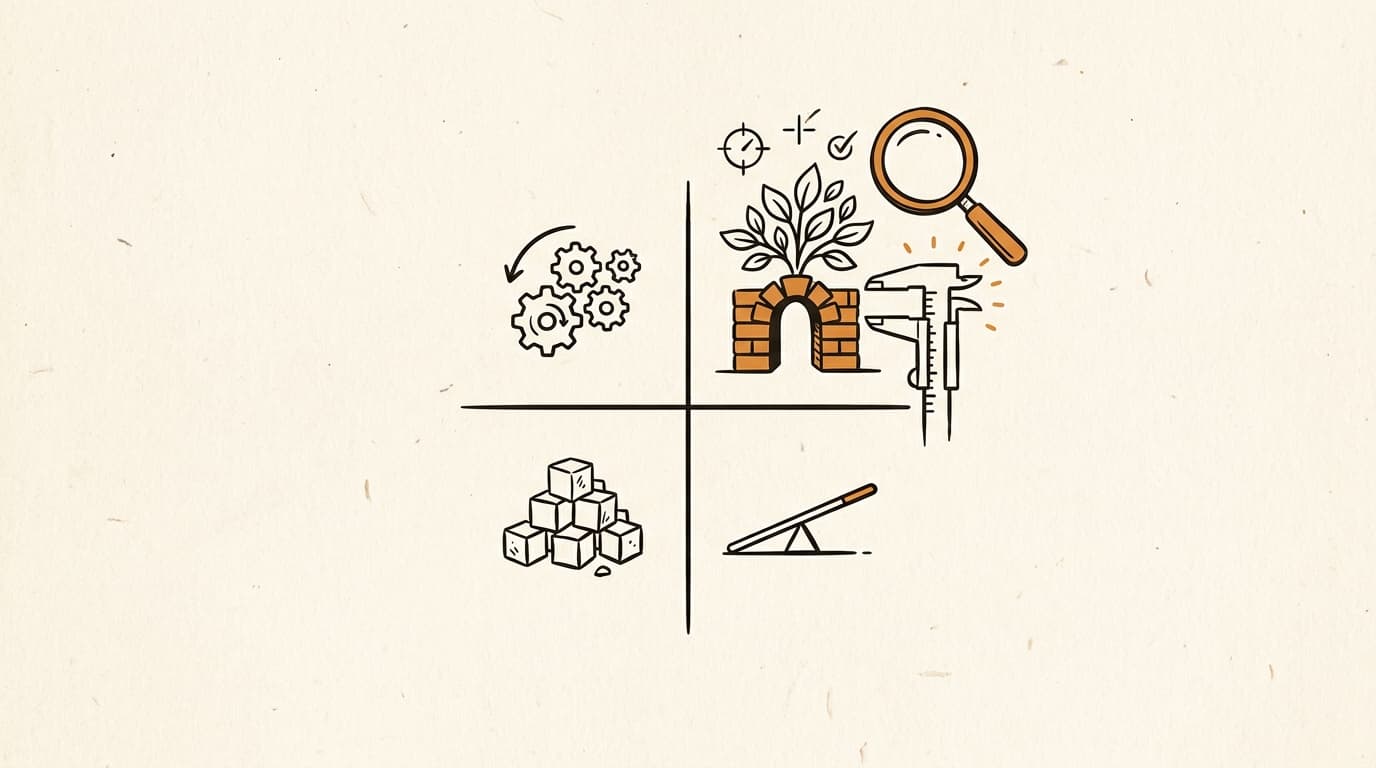
An AI use case prioritization matrix scores candidate ideas on two axes, impact and feasibility, then sorts them into four quadrants. It exists to answer one question: which single use case should this marketing team pilot next.
It is deliberately blunt. Most prioritization debates stall because every idea sounds reasonable in the abstract. Putting impact and feasibility on the same grid forces a comparison, and a comparison usually produces a decision. The matrix does not need to be precise. It needs to be shared, so the team is arguing about the same thing.
The version below is the one used to scope Prova's own operator and leader sprints. It fits on one page and takes about an hour with the right people in the room.
What is an AI use case prioritization matrix?
An AI use case prioritization matrix is a two-by-two grid. One axis is impact: how much the use case changes a metric or removes hours from someone's week. The other axis is feasibility: how easily one person can build and test it in a short window with tools the team already has.
The two axes matter because they filter different kinds of bad idea. A high-impact, low-feasibility use case is a project, not a pilot. A high-feasibility, low-impact use case is a distraction that looks productive. Only the high-impact, high-feasibility quadrant earns a pilot this quarter.
That is the whole logic. It is not a scoring model with weighted coefficients. It is a way to stop a team from spending a month on the interesting-but-hard idea when a boring-but-shippable one is sitting right there.
How do you score AI use cases for a marketing team?
Score each use case from 1 to 5 on impact and 1 to 5 on feasibility. Use the same rubric for every row so the numbers mean the same thing across the list.
| Score | Impact means | Feasibility means |
|---|---|---|
| 5 | Moves a reported metric or frees most of a person's week | One person can build and test it in under two weeks |
| 3 | Improves a workflow but the gain is partial or hard to see | Needs some data cleanup or a tool the team does not own yet |
| 1 | Nice in theory, no clear number or hour attached | Needs new systems, approvals, or a dedicated engineer |
Impact should be tied to something the team already tracks: cycle time, conversion, cost per lead, hours per week. Feasibility should be honest about who builds it. If the answer is "nobody on this team," the feasibility score is a 1 no matter how clever the idea is.
Which AI use cases should you pilot first?
The one in the top-right cell: high impact, high feasibility.
| Low feasibility | High feasibility | |
|---|---|---|
| High impact | Sponsor it, do not pilot it | Pilot this one now |
| Low impact | Ignore it | Automate only if capacity is spare |
The top-right use case is the one to write into a one-page pilot brief. It has a real number attached and a person who can build it soon. That combination is rare enough that when it appears, the team should take it rather than keep comparing.
The top-left cell is often where enthusiasm lives. The idea is genuinely valuable, but it needs a sponsor, data access, or a build partner first. Name that dependency and park the idea; do not let it absorb the sprint. The bottom-right cell is where teams quietly waste weeks, automating something that never mattered. The bottom-left cell is a no.
How do you apply the prioritization matrix?
Start by listing candidates in plain language, one per row. Pull them from the AI workflow audit template rather than from a brainstorm, so every row points at a real task someone does. Then score impact and feasibility on the shared rubric, and plot each row.
Pick the single use case in the high-impact, high-feasibility quadrant. If two tie, choose the one with the shorter path to a testable result. Write down the metric it should move, the owner, and the date you will review it. That note is what turns a grid into a decision.
Then resist the urge to keep scoring. Re-score the shortlist only after the pilot returns evidence. When you are ready to run it, the guide to running an AI pilot on a marketing team covers the measurement side, and the AI readiness scorecard helps you check whether the team can support the work before you start.